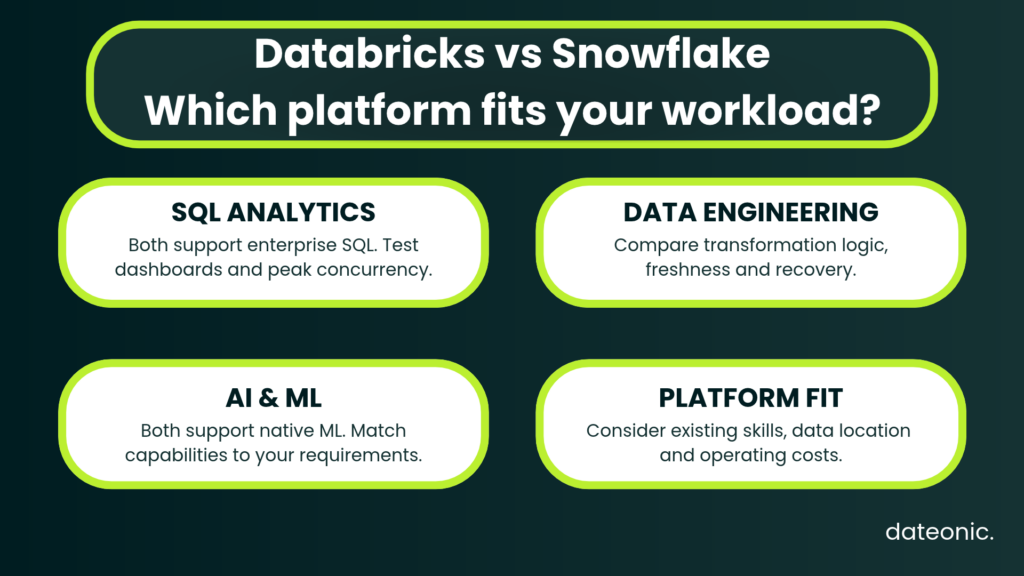
Choose Databricks when your platform needs center on substantial data engineering, custom model development and analytics over a shared lakehouse. Choose Snowflake when an established SQL operating model, warehouse analytics and data collaboration are the stronger fit.
Both now support enterprise SQL, native machine learning and open table formats. The decision is which platform meets your production requirements with manageable engineering and operational work.
Which platform should you shortlist?
Start with the workloads your team must deliver and support. A SQL-heavy Snowflake estate does not need a migration simply because AI has entered the roadmap; an established Databricks estate does not need a second warehouse simply because reporting demand has grown.
| Decision area | Databricks | Snowflake |
|---|---|---|
| Architecture | Lakehouse with Delta Lake and Apache Iceberg support; Unity Catalog governs data and AI assets | Managed platform with native Snowflake tables and Apache Iceberg options; Horizon Catalog supports discovery and governance |
| SQL and BI | SQL warehouses with Photon; serverless adds intelligent workload management | Virtual warehouses; separate warehouses isolate compute, while multi-cluster configurations address concurrency |
| Data engineering | Spark-based processing and Lakeflow pipelines in SQL and Python | SQL transformations, dynamic tables, Snowpark and streaming ingestion |
| AI and ML | MLflow, feature engineering, model training, serving and foundation model APIs | Snowflake ML for custom models; Cortex for AI functions, search, analysis and agents |
| Open data | Delta and Iceberg interoperability depends on table features, catalog and client compatibility | Iceberg separates format choice from the choice of Snowflake compute; catalog and storage modes affect operations |
| Initial fit | Teams building complex pipelines and custom ML alongside analytics | Teams extending a SQL-centered platform and its governed data products |
If you are still considering BigQuery, Microsoft Fabric or an AWS analytics stack, begin with our enterprise data platform comparison.
What changes when you choose the architecture?
The architectural decision is who manages the table, catalog, compute and storage lifecycle. “Lakehouse versus warehouse” alone no longer describes the available configurations. For a broader architecture overview, see our data warehouse vs data lake vs data lakehouse comparison.
Databricks supports Delta Lake and Apache Iceberg tables. In the current AWS documentation, managed Iceberg tables require Unity Catalog, Databricks Runtime 16.4 LTS or later when using runtime compute, and a workspace with serverless compute enabled for metadata maintenance.
Predictive optimization and serverless connectivity to the backing storage are also required. Foreign Iceberg tables are read-only in Databricks and have more limited platform support. These are different operating models, despite sharing a table format. See the Databricks Iceberg documentation.
Snowflake’s native tables use its internally optimized columnar format. Its Iceberg tables offer an open-format alternative, including data in customer-managed object storage.
Snowflake supports different catalog and storage configurations, so “Snowflake requires proprietary storage” is incorrect. Storage ownership also changes recovery responsibilities: Iceberg tables on customer-managed external volumes do not receive Snowflake Fail-safe protection. See Snowflake architecture and Iceberg table options.
For an enterprise using multiple engines, validate the exact combination of table format, reader/writer version, catalog and credentials. Being able to read Parquet files does not establish that an engine correctly interprets table snapshots, deletes or access policies.
Open data formats improve options; they do not automatically make applications, governance rules or operating procedures portable.
Capabilities were checked against official documentation in October 2026. The Databricks references here primarily describe AWS; verify the equivalent cloud, region, runtime, edition and feature availability for the deployment you plan to run.
Can both platforms serve enterprise SQL and BI?
Yes. Databricks SQL is a warehouse service for SQL workloads, so a comparison based on Snowflake SQL versus a general-purpose Spark cluster misses the relevant Databricks option.
Databricks offers classic, pro and serverless SQL warehouses. Photon is included across the warehouse types; serverless also provides intelligent workload management for changing query demand.
Availability and setup requirements still apply. For a BI evaluation, use the proposed SQL warehouse type and actual dashboard queries rather than assuming analysts must manage Spark clusters.
Snowflake virtual warehouses provide independent compute resources. Separate warehouses let teams separate workloads, while multi-cluster warehouses add clusters to handle concurrency when demand rises.
Scaling out concurrency is different from accelerating one expensive query. Queries can still queue when configured capacity is insufficient. Multi-cluster warehouses require Enterprise Edition or higher.
See Snowflake’s compute architecture, multi-cluster warehouse behavior and edition requirements.
For a finance reporting team, the useful comparison is the full reporting path: semantic definitions, access controls, dashboard refreshes, concurrent users and the work needed to support them.
Retain a working Snowflake reporting estate unless the alternative demonstrates a meaningful improvement. Where governed data already lives in Databricks, test Databricks SQL before introducing another serving platform and another copy of the reporting dataset.
How do data engineering and streaming differ?
Databricks is a strong candidate when pipelines require Spark transformations alongside SQL and Python development. Snowflake is a strong candidate when transformations fit the team’s existing SQL and Snowpark operating model. In both cases, ingestion speed is only one part of the freshness requirement.
Lakeflow pipelines build on Apache Spark Declarative Pipelines for batch and streaming processing. They support SQL and Python, with use cases including cloud storage ingestion, message-bus ingestion and incremental transformations. This fits teams that need one development environment for pipeline logic and downstream model features.
Snowflake offers Snowpipe Streaming for streaming ingestion, while dynamic tables materialize query results and manage refresh dependencies toward a target lag. Target lag expresses a freshness objective; actual lag can exceed it when refreshes take longer than expected. Dynamic tables are not a guarantee of a particular end-to-end event-processing latency.
For an inventory pipeline, measure time from the source event to the usable stock position. Include late events, duplicate deliveries, schema changes, interrupted ingestion and replay after an outage. A fast ingest path that leaves downstream transformations stale does not satisfy the business requirement.
Which platform fits your AI and ML workflow?
Separate custom model engineering from applying managed AI to existing data. Both platforms cover these needs, but their fit depends on your frameworks, deployment requirements and where the governed training data lives.
Databricks integrates feature engineering, MLflow experiment tracking, model training and model serving. Its ML platform also provides foundation model APIs and production monitoring capabilities.
This is a relevant shortlist when Python-based model development and data engineering already share the same platform. Use the Databricks ML lifecycle documentation to match the required training and serving paths to supported compute.
Snowflake’s ML platform includes a feature store, experiment tracking, model registry, inference and observability. Its Container Runtime supports model training on CPU and GPU compute. Treating Snowflake as merely a SQL database with external ML integrations understates its current scope.
Snowflake Cortex separately provides AI functions, Cortex Search, Cortex Analyst and agents. An organization whose first AI requirement is search or analysis over data already governed in Snowflake should evaluate those services before moving its data to another platform.
For custom ML, validate library compatibility, training-data reproducibility, feature consistency and deployment behavior. For an AI assistant, validate retrieval authorization, answer quality on representative questions, evaluation coverage and inference latency.
A successful model demo is insufficient evidence that the production system will answer correctly for users with different permissions.
How do Unity Catalog and Horizon Catalog compare?
Both provide governance capabilities, but governance must be evaluated along the actual access path. A catalog entry does not prove that every external reader applies the same policies.
Unity Catalog governs Databricks data and AI assets, including tables, views, volumes, functions and models. Its capabilities include access control, row and column filtering, lineage and auditing. Managed and external assets differ in who controls the underlying storage lifecycle.
For more detail, see our Databricks Unity Catalog data governance guide.
Snowflake Horizon Catalog combines discovery, lineage and governance across Snowflake and supported external integrations. It includes sensitive-data protection and policy capabilities, with enforcement conditions attached to the feature and access path.
Snowflake’s edition matrix places column masking, row access policies and access history in Enterprise Edition and above.
In either platform, test a restricted user, a service identity and a deliberately unauthorized access attempt. Repeat the test through the BI connector, notebook or external engine that will actually read the data.
If a reader can use independent object-storage credentials, treat that as a separate authorization path requiring storage-level controls.
Historical data access is another design decision. Snowflake Time Travel and table snapshot/version retention help with recovery and reproducibility; they are not substitutes for a governance catalog or a complete disaster-recovery plan.
Which integrations and sharing patterns matter?
Prioritize the integrations your business actually uses, including their identity and data-movement behavior. A long partner list does not establish that a particular connector meets your refresh, security or recovery requirements.
Snowflake’s Secure Data Sharing lets other Snowflake accounts consume selected shared objects. Cross-region and cross-cloud arrangements need their own replication, fulfillment and cost review; do not assume every sharing topology avoids data movement.
Databricks’ OpenSharing supports sharing data and AI assets beyond an organization, including recipients outside Databricks. Supported objects and governance behavior differ between Databricks-to-Databricks and open-recipient protocols.
Iceberg-compatible access offers another integration route. For either platform, distinguish sharing a governed data product from giving an external engine direct storage access.
For BI and transformation tools, test the production connector with service authentication, pushdown behavior, refresh scheduling and failure handling. Existing integrations can justify retaining a platform even when another platform supports a similar feature.
Using both platforms can be reasonable when each has a defined workload. Dateonic’s Lakehouse Federation guide explains an external-query approach.
For any coexistence design, name the authoritative dataset, the owner of each transformation and the freshness contract. Account for source-system load when querying remotely and reconciliation work when copying data.
How should you compare performance?
Benchmark the production workload and its service levels. Neither a vendor benchmark nor a broad claim that one platform is faster for SQL or ETL establishes the result for your queries, table layout and concurrency.
Databricks’ Photon engine accelerates supported SQL and DataFrame operations; it does not mean every UDF, transformation or streaming operation runs through Photon. Snowflake’s warehouse sizing and concurrency controls address different sources of query latency.
Record the actual configuration and examine queueing separately from execution time.
| Test | Keep comparable | Evidence to collect |
|---|---|---|
| Dashboard peak | Queries, permissions, data freshness and concurrent users | End-to-end p50/p95 latency, queue time and failures |
| Pipeline run | Source snapshot, transformation semantics and output checks | Completion time, rows reconciled and retry/recovery behavior |
| Interactive analysis | Query mix, cache conditions and warehouse start state | Cold and warm response times, including startup |
| AI workload | Dataset, quality target and serving requirements | Answer or model quality, latency and failed requests |
Allow each platform appropriate tuning, but record the tuning effort. Verify output correctness before comparing speed, and include unsuccessful runs when assessing reliability and cost. These are proposed evaluation criteria, not benchmarks executed for this article.
How do pricing and TCO affect the shortlist?
Compare the cost of meeting the same workload requirement. A Databricks Unit and a Snowflake credit are different billing units; their unit prices cannot establish which platform is cheaper.
For Databricks classic compute, include DBUs plus cloud virtual machines, disks and networking. For serverless services, the DBU charge includes the underlying virtual machine cost, so do not add that VM cost again. Storage and applicable networking or service charges still need attention. These boundaries are described in Databricks cost guidance.
Snowflake costs include warehouse compute, serverless features, applicable cloud-services usage, storage and data transfer. AI and container-based workloads can introduce additional service-specific meters.
Virtual warehouses use per-second credit billing with a 60-second minimum each time they start or resume, so frequent stop/start patterns need evaluation. See overall Snowflake costs and compute billing.
For predictable BI, examine peak concurrency and warehouse utilization. For intermittent analytics, examine startup, suspension and minimum billing.
For mixed pipelines, BI and ML, examine whether shared data and operations reduce duplication enough to justify the platform complexity. These are measurement priorities, not predetermined cost winners.
The separate Databricks vs Snowflake TCO guide covers the financial model, labor, transition costs and scenario analysis. Use it after defining the architecture and workload assumptions.
Which enterprise scenario matches your decision?
Choose the next workload deliberately; an estate-wide replacement is not the default. The scenarios below are illustrative recommendations based on the capabilities discussed above, not reported client results.
| Enterprise situation | Recommended starting position | What could change the decision? |
|---|---|---|
| Finance and commercial reporting already run reliably in Snowflake; the team mostly develops SQL | Retain Snowflake and evaluate new analytics or Cortex requirements there | A representative alternative removes a documented constraint and justifies migration work |
| Spark/Python pipelines and custom models already run on Databricks; a reporting team needs governed SQL access | Evaluate Databricks SQL over the existing governed tables | Required connector behavior, user experience or service levels cannot be met |
| A new platform must serve complex transformations, model development and reporting over shared data | Shortlist Databricks, while testing Snowflake ML and transformation options against the same requirements | Existing Snowflake skills, integrations and a successful production-like trial favor Snowflake |
| Several engines must access common open tables | Compare concrete Iceberg catalog, storage and read/write configurations on both platforms | Required operations, table features or authorization cannot be supported across the selected engines |
| Snowflake data products must remain, while a separate engineering workload favors Databricks | Use a bounded coexistence design with explicit ownership | Duplication, reconciliation or cross-platform access adds more operational work than the extra platform resolves |
What should you validate before committing?
Turn the evaluation into a scoped decision record. State which platform owns the workload, which existing dependencies remain, and who accepts the operating responsibilities.
Attach the performance, access and recovery evidence rather than treating a feature checklist as production approval. Our Databricks PoC success criteria provide a practical validation framework.
For a migration, check the change surface before committing: SQL semantics and UDFs, downstream data contracts, service identities, deployment processes and the ability to reverse the cutover. K
eep Snowflake available until the agreed reconciliation and rollback conditions are satisfied. A workload can pass its technical trial while dependent reports still prevent decommissioning.
Dateonic is a Databricks-focused engineering consultancy. Its Databricks implementation consulting covers repeatable Terraform platform setup, data pipelines, Unity Catalog governance, release processes and production handover. Its migration service covers assessment, target architecture, planning and implementation through production readiness.
If Databricks is on your shortlist, use a Databricks migration assessment with Dateonic to identify which workloads should move, which should remain and what evidence is needed before committing to the transition.